SCIoI Alumni

Marah Halawa

Doctoral Researcher

Computer Science

Marah joined SCIoI as a doctoral researcher in October 2020.


TU Berlin


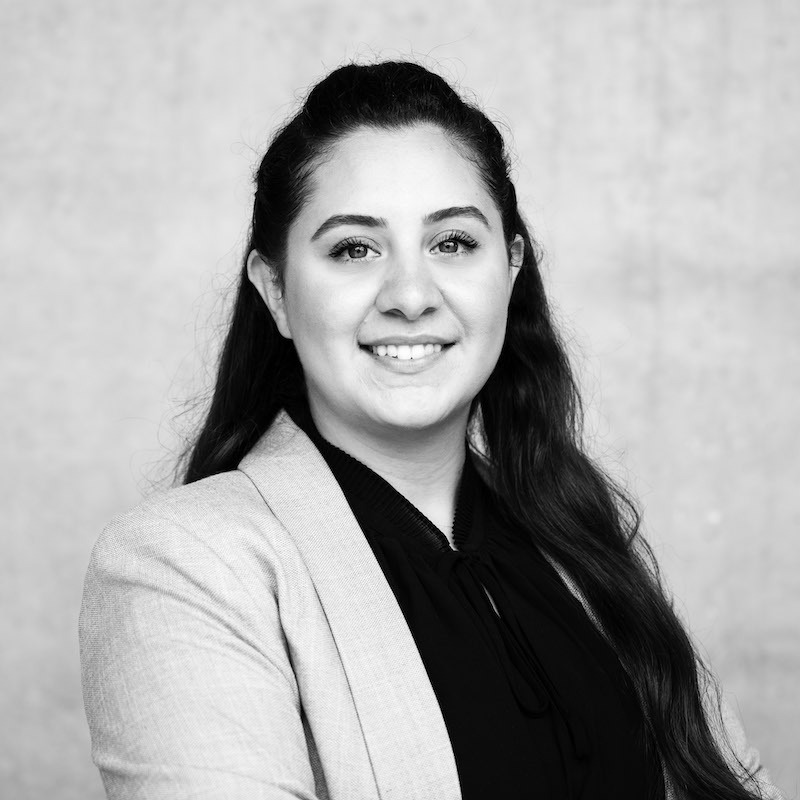
Photo: SCIoI

← Alumni Overview

Marah Halawa

Marah Halawa

Photo: SCIoI

Marah Halawa is a computer scientist specializing in machine learning and artificial intelligence, with experience applying these methods to areas including speech recognition, facial expression recognition, and fraud detection.

She joined SCIoI as a doctoral researcher in October 2020.

Marah received her M.Sc. in Computer Science from TU Berlin in 2019, where she specialized in Machine Learning and Artificial Intelligence and worked on many machine learning applications. After graduation, she started a full-time position as a Data Scientist, where she developed a deep-learning-based system for fraud detection.

At SCIoI, Marah worked on Project 29. Her research focused on enabling visual understanding in modularized and hierarchical temporal vision systems for closed perception-action loops.


Projects

Marah Halawa is member of:


6984777 Halawa 1 apa 50 date desc year 19862 https://www.scienceofintelligence.de/wp-content/plugins/zotpress/
%7B%22status%22%3A%22success%22%2C%22updateneeded%22%3Afalse%2C%22instance%22%3Afalse%2C%22meta%22%3A%7B%22request_last%22%3A0%2C%22request_next%22%3A0%2C%22used_cache%22%3Atrue%7D%2C%22data%22%3A%5B%7B%22key%22%3A%22QKAHMER8%22%2C%22library%22%3A%7B%22id%22%3A6984777%7D%2C%22meta%22%3A%7B%22creatorSummary%22%3A%22Halawa%20et%20al.%22%2C%22parsedDate%22%3A%222024-06%22%2C%22numChildren%22%3A1%7D%2C%22bib%22%3A%22%26lt%3Bdiv%20class%3D%26quot%3Bcsl-bib-body%26quot%3B%20style%3D%26quot%3Bline-height%3A%202%3B%20padding-left%3A%201em%3B%20text-indent%3A-1em%3B%26quot%3B%26gt%3B%5Cn%20%20%26lt%3Bdiv%20class%3D%26quot%3Bcsl-entry%26quot%3B%26gt%3BHalawa%2C%20M.%2C%20Blume%2C%20F.%2C%20Bideau%2C%20P.%2C%20Maier%2C%20M.%2C%20Rahman%2C%20R.%20A.%2C%20%26amp%3B%20Hellwich%2C%20O.%20%282024%29.%20Multi-Task%20Multi-Modal%20Self-Supervised%20Learning%20for%20Facial%20Expression%20Recognition.%20%26lt%3Bi%26gt%3B2024%20IEEE%5C%2FCVF%20Conference%20on%20Computer%20Vision%20and%20Pattern%20Recognition%20Workshops%20%28CVPRW%29%26lt%3B%5C%2Fi%26gt%3B%2C%204604%26%23x2013%3B4614.%20%26lt%3Ba%20class%3D%26%23039%3Bzp-DOIURL%26%23039%3B%20href%3D%26%23039%3Bhttps%3A%5C%2F%5C%2Fdoi.org%5C%2F10.1109%5C%2FCVPRW63382.2024.00463%26%23039%3B%26gt%3Bhttps%3A%5C%2F%5C%2Fdoi.org%5C%2F10.1109%5C%2FCVPRW63382.2024.00463%26lt%3B%5C%2Fa%26gt%3B%26lt%3B%5C%2Fdiv%26gt%3B%5Cn%26lt%3B%5C%2Fdiv%26gt%3B%22%2C%22data%22%3A%7B%22itemType%22%3A%22conferencePaper%22%2C%22title%22%3A%22Multi-Task%20Multi-Modal%20Self-Supervised%20Learning%20for%20Facial%20Expression%20Recognition%22%2C%22creators%22%3A%5B%7B%22creatorType%22%3A%22author%22%2C%22firstName%22%3A%22Marah%22%2C%22lastName%22%3A%22Halawa%22%7D%2C%7B%22creatorType%22%3A%22author%22%2C%22firstName%22%3A%22Florian%22%2C%22lastName%22%3A%22Blume%22%7D%2C%7B%22creatorType%22%3A%22author%22%2C%22firstName%22%3A%22Pia%22%2C%22lastName%22%3A%22Bideau%22%7D%2C%7B%22creatorType%22%3A%22author%22%2C%22firstName%22%3A%22Martin%22%2C%22lastName%22%3A%22Maier%22%7D%2C%7B%22creatorType%22%3A%22author%22%2C%22firstName%22%3A%22Rasha%20Abdel%22%2C%22lastName%22%3A%22Rahman%22%7D%2C%7B%22creatorType%22%3A%22author%22%2C%22firstName%22%3A%22Olaf%22%2C%22lastName%22%3A%22Hellwich%22%7D%5D%2C%22abstractNote%22%3A%22Human%20communication%20is%20multi-modal%3B%20e.g.%2C%20face-to-face%20interaction%20involves%20auditory%20signals%20%28speech%29%20and%20visual%20signals%20%28face%20movements%20and%20hand%20gestures%29.%20Hence%2C%20it%20is%20essential%20to%20exploit%20multiple%20modalities%20when%20designing%20machine%20learning-based%20facial%20expression%20recognition%20systems.%20In%20addition%2C%20given%20the%20ever-growing%20quantities%20of%20video%20data%20that%20capture%20human%20facial%20expressions%2C%20such%20systems%20should%20utilize%20raw%20unlabeled%20videos%20without%20requiring%20expensive%20annotations.%20Therefore%2C%20in%20this%20work%2C%20we%20employ%20a%20multitask%20multi-modal%20self-supervised%20learning%20method%20for%20facial%20expression%20recognition%20from%20in-the-wild%20video%20data.%20Our%20model%20combines%20three%20self-supervised%20objective%20functions%3A%20First%2C%20a%20multi-modal%20contrastive%20loss%2C%20that%20pulls%20diverse%20data%20modalities%20of%20the%20same%20video%20together%20in%20the%20representation%20space.%20Second%2C%20a%20multi-modal%20clustering%20loss%20that%20preserves%20the%20semantic%20structure%20of%20input%20data%20in%20the%20representation%20space.%20Finally%2C%20a%20multi-modal%20data%20reconstruction%20loss.%20We%20conduct%20a%20comprehensive%20study%20on%20this%20multimodal%20multi-task%20self-supervised%20learning%20method%20on%20three%20facial%20expression%20recognition%20benchmarks.%20To%20that%20end%2C%20we%20examine%20the%20performance%20of%20learning%20through%20different%20combinations%20of%20self-supervised%20tasks%20on%20the%20facial%20expression%20recognition%20downstream%20task.%20Our%20model%20ConCluGen%20outperforms%20several%20multi-modal%20self-supervised%20and%20fully%20supervised%20baselines%20on%20the%20CMU-MOSEI%20dataset.%20Our%20results%20generally%20show%20that%20multi-modal%20self-supervision%20tasks%20offer%20large%20performance%20gains%20for%20challenging%20tasks%20such%20as%20facial%20expression%20recognition%2C%20while%20also%20reducing%20the%20amount%20of%20manual%20annotations%20required.%20We%20release%20our%20pre-trained%20models%20as%20well%20as%20source%20code%20publicly1.%22%2C%22proceedingsTitle%22%3A%222024%20IEEE%5C%2FCVF%20Conference%20on%20Computer%20Vision%20and%20Pattern%20Recognition%20Workshops%20%28CVPRW%29%22%2C%22conferenceName%22%3A%222024%20IEEE%5C%2FCVF%20Conference%20on%20Computer%20Vision%20and%20Pattern%20Recognition%20Workshops%20%28CVPRW%29%22%2C%22date%22%3A%222024-06%22%2C%22eventPlace%22%3A%22%22%2C%22DOI%22%3A%2210.1109%5C%2FCVPRW63382.2024.00463%22%2C%22ISBN%22%3A%22%22%2C%22citationKey%22%3A%22%22%2C%22url%22%3A%22https%3A%5C%2F%5C%2Fieeexplore.ieee.org%5C%2Fdocument%5C%2F10678641%22%2C%22ISSN%22%3A%222160-7516%22%2C%22language%22%3A%22%22%2C%22collections%22%3A%5B%5D%2C%22dateModified%22%3A%222026-06-22T12%3A01%3A10Z%22%7D%7D%2C%7B%22key%22%3A%22DCZ2RZ22%22%2C%22library%22%3A%7B%22id%22%3A6984777%7D%2C%22meta%22%3A%7B%22creatorSummary%22%3A%22Halawa%20et%20al.%22%2C%22parsedDate%22%3A%222022%22%2C%22numChildren%22%3A1%7D%2C%22bib%22%3A%22%26lt%3Bdiv%20class%3D%26quot%3Bcsl-bib-body%26quot%3B%20style%3D%26quot%3Bline-height%3A%202%3B%20padding-left%3A%201em%3B%20text-indent%3A-1em%3B%26quot%3B%26gt%3B%5Cn%20%20%26lt%3Bdiv%20class%3D%26quot%3Bcsl-entry%26quot%3B%26gt%3BHalawa%2C%20M.%2C%20Hellwich%2C%20O.%2C%20%26amp%3B%20Bideau%2C%20P.%20%282022%29.%20Action-Based%20Contrastive%20Learning%20for%20Trajectory%20Prediction.%20In%20S.%20Avidan%2C%20G.%20Brostow%2C%20M.%20Ciss%26%23xE9%3B%2C%20G.%20M.%20Farinella%2C%20%26amp%3B%20T.%20Hassner%20%28Eds.%29%2C%20%26lt%3Bi%26gt%3BComputer%20Vision%20%26%23x2013%3B%20ECCV%202022%26lt%3B%5C%2Fi%26gt%3B%20%28Vol.%2013699%2C%20pp.%20143%26%23x2013%3B159%29.%20Springer%20Nature%20Switzerland.%20%26lt%3Ba%20class%3D%26%23039%3Bzp-DOIURL%26%23039%3B%20href%3D%26%23039%3Bhttps%3A%5C%2F%5C%2Fdoi.org%5C%2F10.1007%5C%2F978-3-031-19842-7_9%26%23039%3B%26gt%3Bhttps%3A%5C%2F%5C%2Fdoi.org%5C%2F10.1007%5C%2F978-3-031-19842-7_9%26lt%3B%5C%2Fa%26gt%3B%26lt%3B%5C%2Fdiv%26gt%3B%5Cn%26lt%3B%5C%2Fdiv%26gt%3B%22%2C%22data%22%3A%7B%22itemType%22%3A%22conferencePaper%22%2C%22title%22%3A%22Action-Based%20Contrastive%20Learning%20for%20Trajectory%20Prediction%22%2C%22creators%22%3A%5B%7B%22creatorType%22%3A%22author%22%2C%22firstName%22%3A%22Marah%22%2C%22lastName%22%3A%22Halawa%22%7D%2C%7B%22creatorType%22%3A%22author%22%2C%22firstName%22%3A%22Olaf%22%2C%22lastName%22%3A%22Hellwich%22%7D%2C%7B%22creatorType%22%3A%22author%22%2C%22firstName%22%3A%22Pia%22%2C%22lastName%22%3A%22Bideau%22%7D%2C%7B%22creatorType%22%3A%22editor%22%2C%22firstName%22%3A%22Shai%22%2C%22lastName%22%3A%22Avidan%22%7D%2C%7B%22creatorType%22%3A%22editor%22%2C%22firstName%22%3A%22Gabriel%22%2C%22lastName%22%3A%22Brostow%22%7D%2C%7B%22creatorType%22%3A%22editor%22%2C%22firstName%22%3A%22Moustapha%22%2C%22lastName%22%3A%22Ciss%5Cu00e9%22%7D%2C%7B%22creatorType%22%3A%22editor%22%2C%22firstName%22%3A%22Giovanni%20Maria%22%2C%22lastName%22%3A%22Farinella%22%7D%2C%7B%22creatorType%22%3A%22editor%22%2C%22firstName%22%3A%22Tal%22%2C%22lastName%22%3A%22Hassner%22%7D%5D%2C%22abstractNote%22%3A%22%22%2C%22proceedingsTitle%22%3A%22Computer%20Vision%20%5Cu2013%20ECCV%202022%22%2C%22conferenceName%22%3A%22%22%2C%22date%22%3A%222022%22%2C%22eventPlace%22%3A%22%22%2C%22DOI%22%3A%2210.1007%5C%2F978-3-031-19842-7_9%22%2C%22ISBN%22%3A%22978-3-031-19841-0%20978-3-031-19842-7%22%2C%22citationKey%22%3A%22%22%2C%22url%22%3A%22https%3A%5C%2F%5C%2Flink.springer.com%5C%2F10.1007%5C%2F978-3-031-19842-7_9%22%2C%22ISSN%22%3A%22%22%2C%22language%22%3A%22en%22%2C%22collections%22%3A%5B%5D%2C%22dateModified%22%3A%222026-06-22T11%3A50%3A40Z%22%7D%7D%2C%7B%22key%22%3A%224YNQ2UHV%22%2C%22library%22%3A%7B%22id%22%3A6984777%7D%2C%22meta%22%3A%7B%22creatorSummary%22%3A%22Halawa%20et%20al.%22%2C%22parsedDate%22%3A%222020%22%2C%22numChildren%22%3A1%7D%2C%22bib%22%3A%22%26lt%3Bdiv%20class%3D%26quot%3Bcsl-bib-body%26quot%3B%20style%3D%26quot%3Bline-height%3A%202%3B%20padding-left%3A%201em%3B%20text-indent%3A-1em%3B%26quot%3B%26gt%3B%5Cn%20%20%26lt%3Bdiv%20class%3D%26quot%3Bcsl-entry%26quot%3B%26gt%3BHalawa%2C%20M.%2C%20W%26%23xF6%3Bllhaf%2C%20M.%2C%20Vellasques%2C%20E.%2C%20Sanz%2C%20U.%20S.%2C%20%26amp%3B%20Hellwich%2C%20O.%20%282020%29.%20%26lt%3Bi%26gt%3BLearning%20Disentangled%20Expression%20Representations%20from%20Facial%20Images%26lt%3B%5C%2Fi%26gt%3B.%20WiCV%20at%20ECCV2020.%20%26lt%3Ba%20class%3D%26%23039%3Bzp-DOIURL%26%23039%3B%20href%3D%26%23039%3Bhttps%3A%5C%2F%5C%2Fdoi.org%5C%2F10.48550%5C%2FarXiv.2008.07001%26%23039%3B%26gt%3Bhttps%3A%5C%2F%5C%2Fdoi.org%5C%2F10.48550%5C%2FarXiv.2008.07001%26lt%3B%5C%2Fa%26gt%3B%26lt%3B%5C%2Fdiv%26gt%3B%5Cn%26lt%3B%5C%2Fdiv%26gt%3B%22%2C%22data%22%3A%7B%22itemType%22%3A%22presentation%22%2C%22title%22%3A%22Learning%20Disentangled%20Expression%20Representations%20from%20Facial%20Images%22%2C%22creators%22%3A%5B%7B%22creatorType%22%3A%22presenter%22%2C%22firstName%22%3A%22Marah%22%2C%22lastName%22%3A%22Halawa%22%7D%2C%7B%22creatorType%22%3A%22presenter%22%2C%22firstName%22%3A%22Manuel%22%2C%22lastName%22%3A%22W%5Cu00f6llhaf%22%7D%2C%7B%22creatorType%22%3A%22presenter%22%2C%22firstName%22%3A%22Eduardo%22%2C%22lastName%22%3A%22Vellasques%22%7D%2C%7B%22creatorType%22%3A%22presenter%22%2C%22firstName%22%3A%22Urko%20S%5Cu00e1nchez%22%2C%22lastName%22%3A%22Sanz%22%7D%2C%7B%22creatorType%22%3A%22presenter%22%2C%22firstName%22%3A%22Olaf%22%2C%22lastName%22%3A%22Hellwich%22%7D%5D%2C%22abstractNote%22%3A%22Face%20images%20are%20subject%20to%20many%20different%20factors%20of%20variation%2C%20especially%20in%20unconstrained%20in-the-wild%20scenarios.%20For%20most%20tasks%20involving%20such%20images%2C%20e.g.%20expression%20recognition%20from%20video%20streams%2C%20having%20enough%20labeled%20data%20is%20prohibitively%20expensive.%20One%20common%20strategy%20to%20tackle%20such%20a%20problem%20is%20to%20learn%20disentangled%20representations%20for%20the%20different%20factors%20of%20variation%20of%20the%20observed%20data%20using%20adversarial%20learning.%20In%20this%20paper%2C%20we%20use%20a%20formulation%20of%20the%20adversarial%20loss%20to%20learn%20disentangled%20representations%20for%20face%20images.%20The%20used%20model%20facilitates%20learning%20on%20single-task%20datasets%20and%20improves%20the%20state-of-the-art%20in%20expression%20recognition%20with%20an%20accuracy%20of60.53%25on%20the%20AffectNetdataset%2C%20without%20using%20any%20additional%20data.%22%2C%22date%22%3A%222020%22%2C%22sessionTitle%22%3A%22%22%2C%22DOI%22%3A%2210.48550%5C%2FarXiv.2008.07001%22%2C%22citationKey%22%3A%22%22%2C%22url%22%3A%22%22%2C%22language%22%3A%22%22%2C%22collections%22%3A%5B%5D%2C%22dateModified%22%3A%222026-09-11T07%3A21%3A46Z%22%7D%7D%5D%7D
Halawa, M., Blume, F., Bideau, P., Maier, M., Rahman, R. A., & Hellwich, O. (2024). Multi-Task Multi-Modal Self-Supervised Learning for Facial Expression Recognition. 2024 IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW), 4604–4614. https://doi.org/10.1109/CVPRW63382.2024.00463
Halawa, M., Hellwich, O., & Bideau, P. (2022). Action-Based Contrastive Learning for Trajectory Prediction. In S. Avidan, G. Brostow, M. Cissé, G. M. Farinella, & T. Hassner (Eds.), Computer Vision – ECCV 2022 (Vol. 13699, pp. 143–159). Springer Nature Switzerland. https://doi.org/10.1007/978-3-031-19842-7_9
Halawa, M., Wöllhaf, M., Vellasques, E., Sanz, U. S., & Hellwich, O. (2020). Learning Disentangled Expression Representations from Facial Images. WiCV at ECCV2020. https://doi.org/10.48550/arXiv.2008.07001

For the Public - Girls’ Day 2022

Research

An overview of our scientific work

See our Research Projects